Human-VLM Collaborative Labeling Framework with Consistency-Guided Viewpoint Optimization for Preference-Based Reinforcement Learning
Abstract
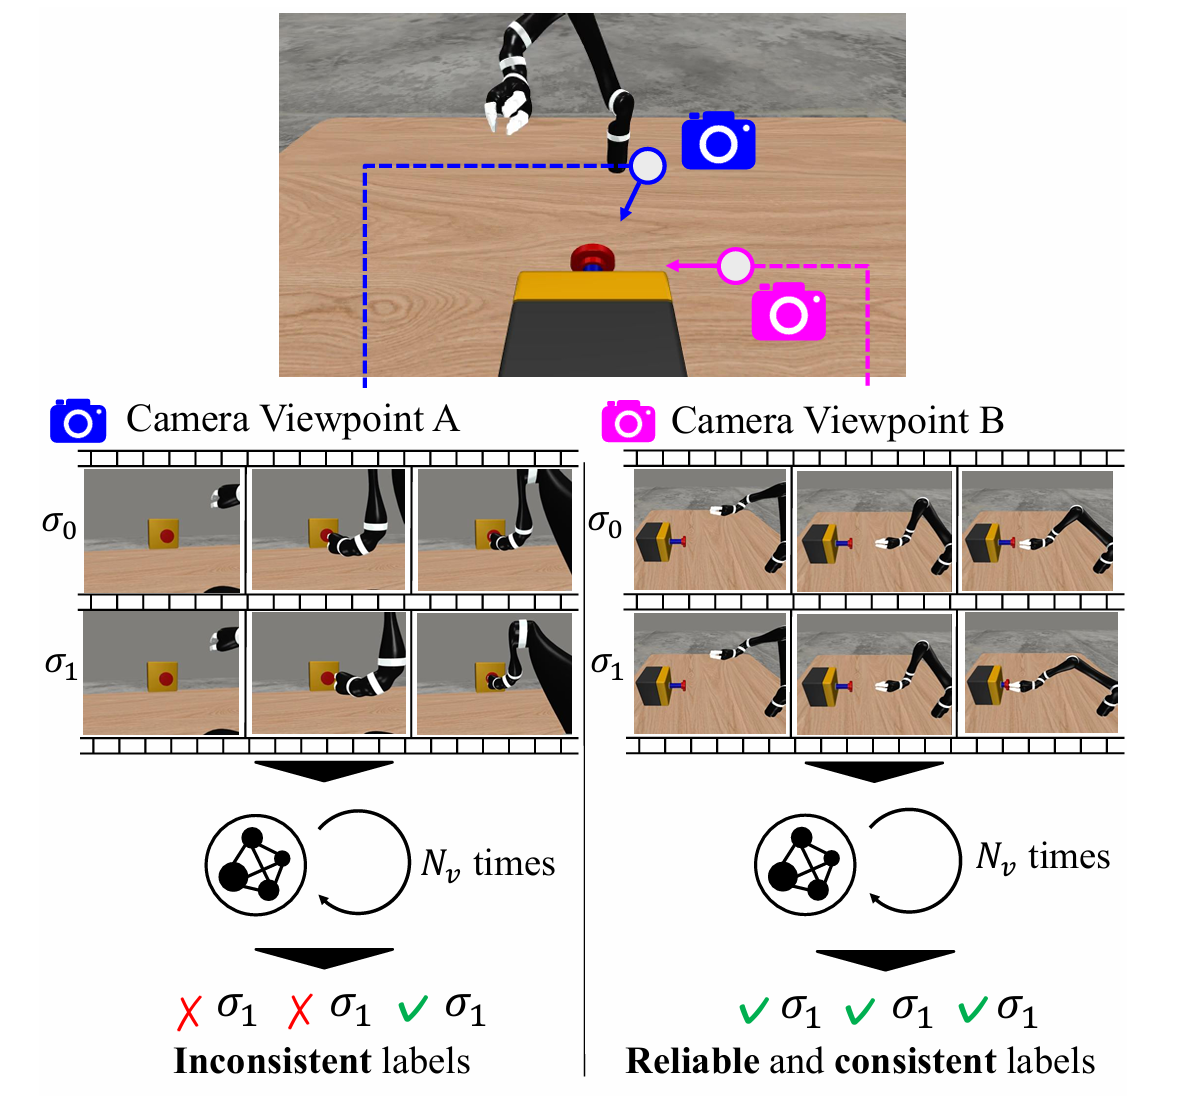
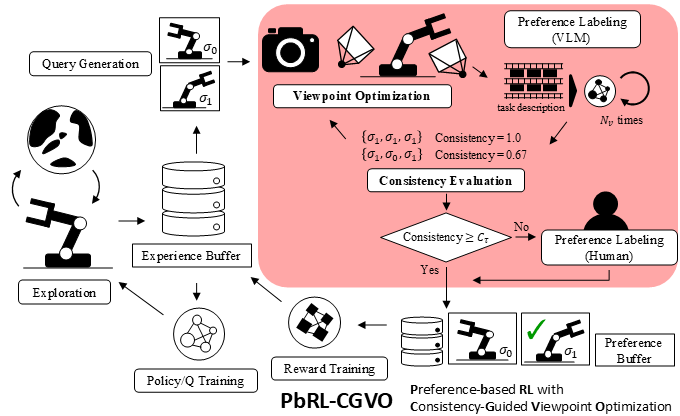
Preference-based reinforcement learning (PbRL) can learn rewards from comparative feedback, but human labeling is costly. This project studies a human-VLM collaborative framework in which label consistency is used as a proxy for VLM reliability, and camera viewpoints are actively optimized to improve preference annotation quality. The method, PbRL-CGVO, uses Bayesian optimization to search for viewpoints that maximize consistency, thereby improving task success while reducing reliance on human queries.
Method Overview
Consistency Estimation
We evaluate the consistency of VLM-generated pairwise preferences across related observations. Consistency serves as a practical proxy for label reliability without requiring dense human supervision.
Viewpoint Optimization with Bayesian Optimization
We search over candidate camera viewpoints using Bayesian optimization to maximize predicted consistency. This active selection policy prioritizes informative views that improve downstream preference labels.
Human-VLM Collaborative Labeling
VLM annotations are used when confidence is high, while uncertain cases are escalated to human feedback. This collaboration reduces annotation cost while maintaining robust reward learning performance.
Results
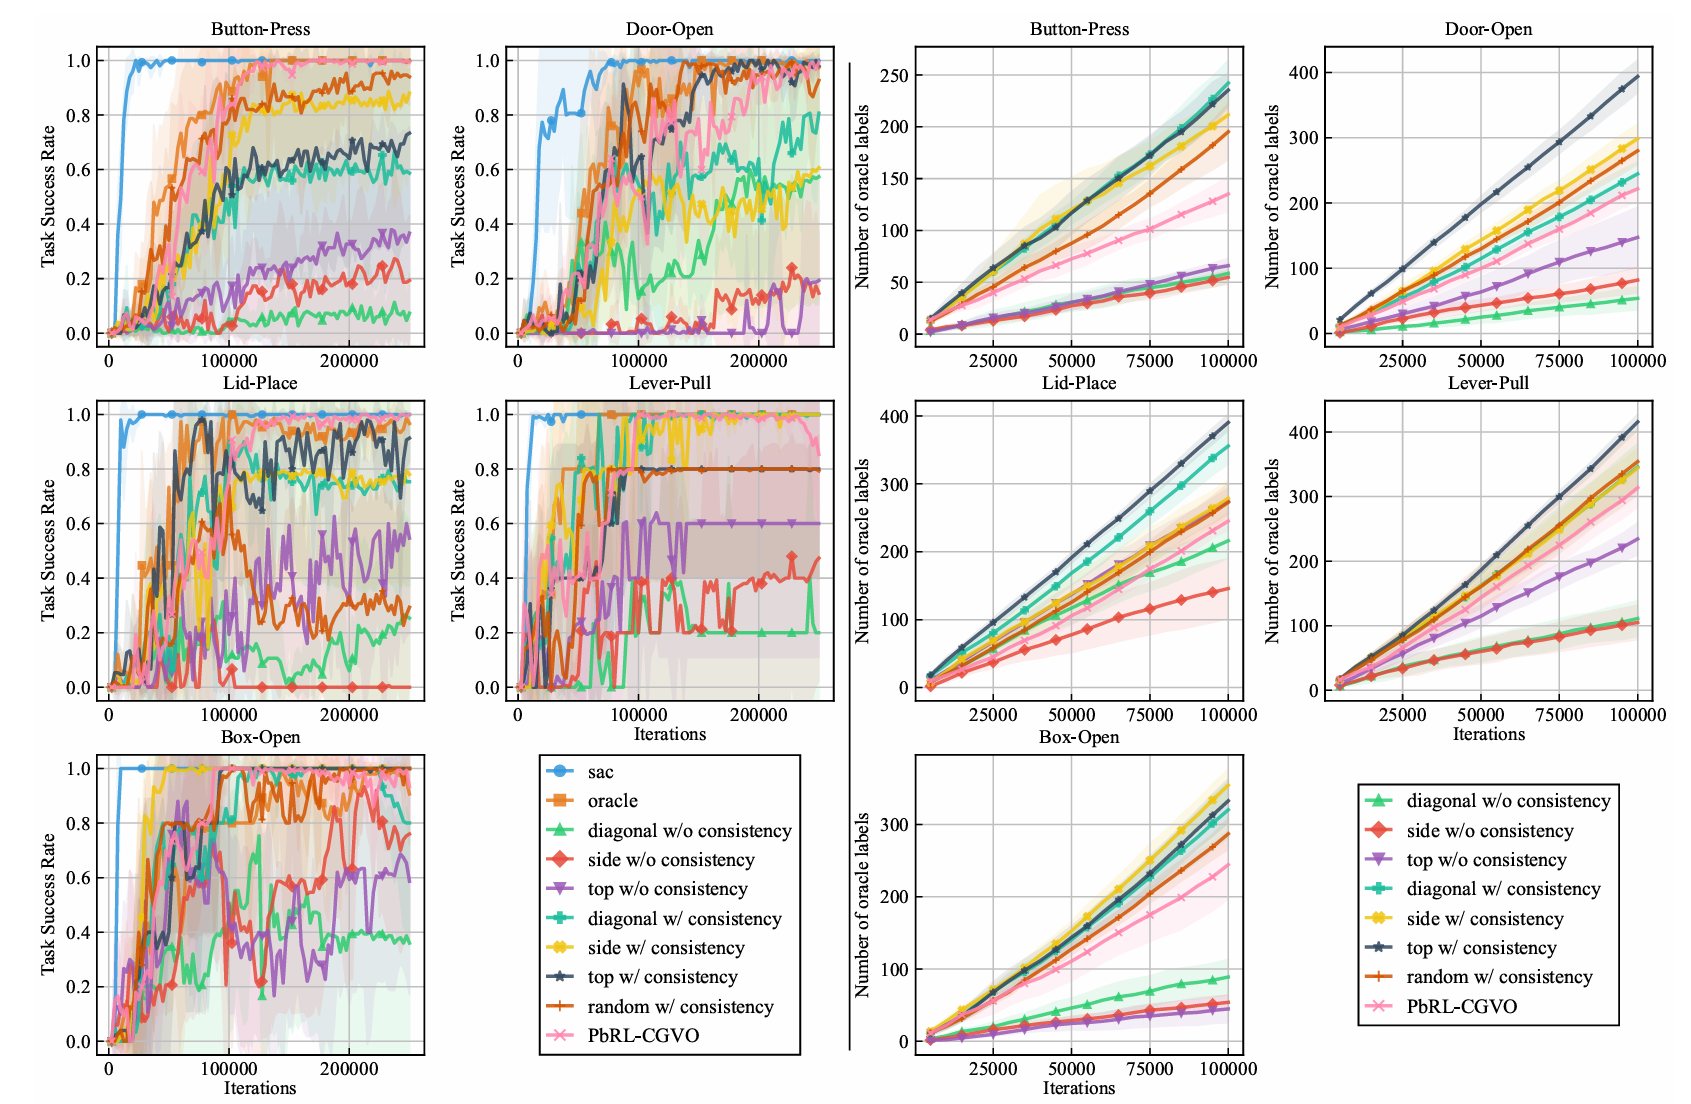
Task performance: viewpoint optimization improves success rates compared with fixed-view baselines.
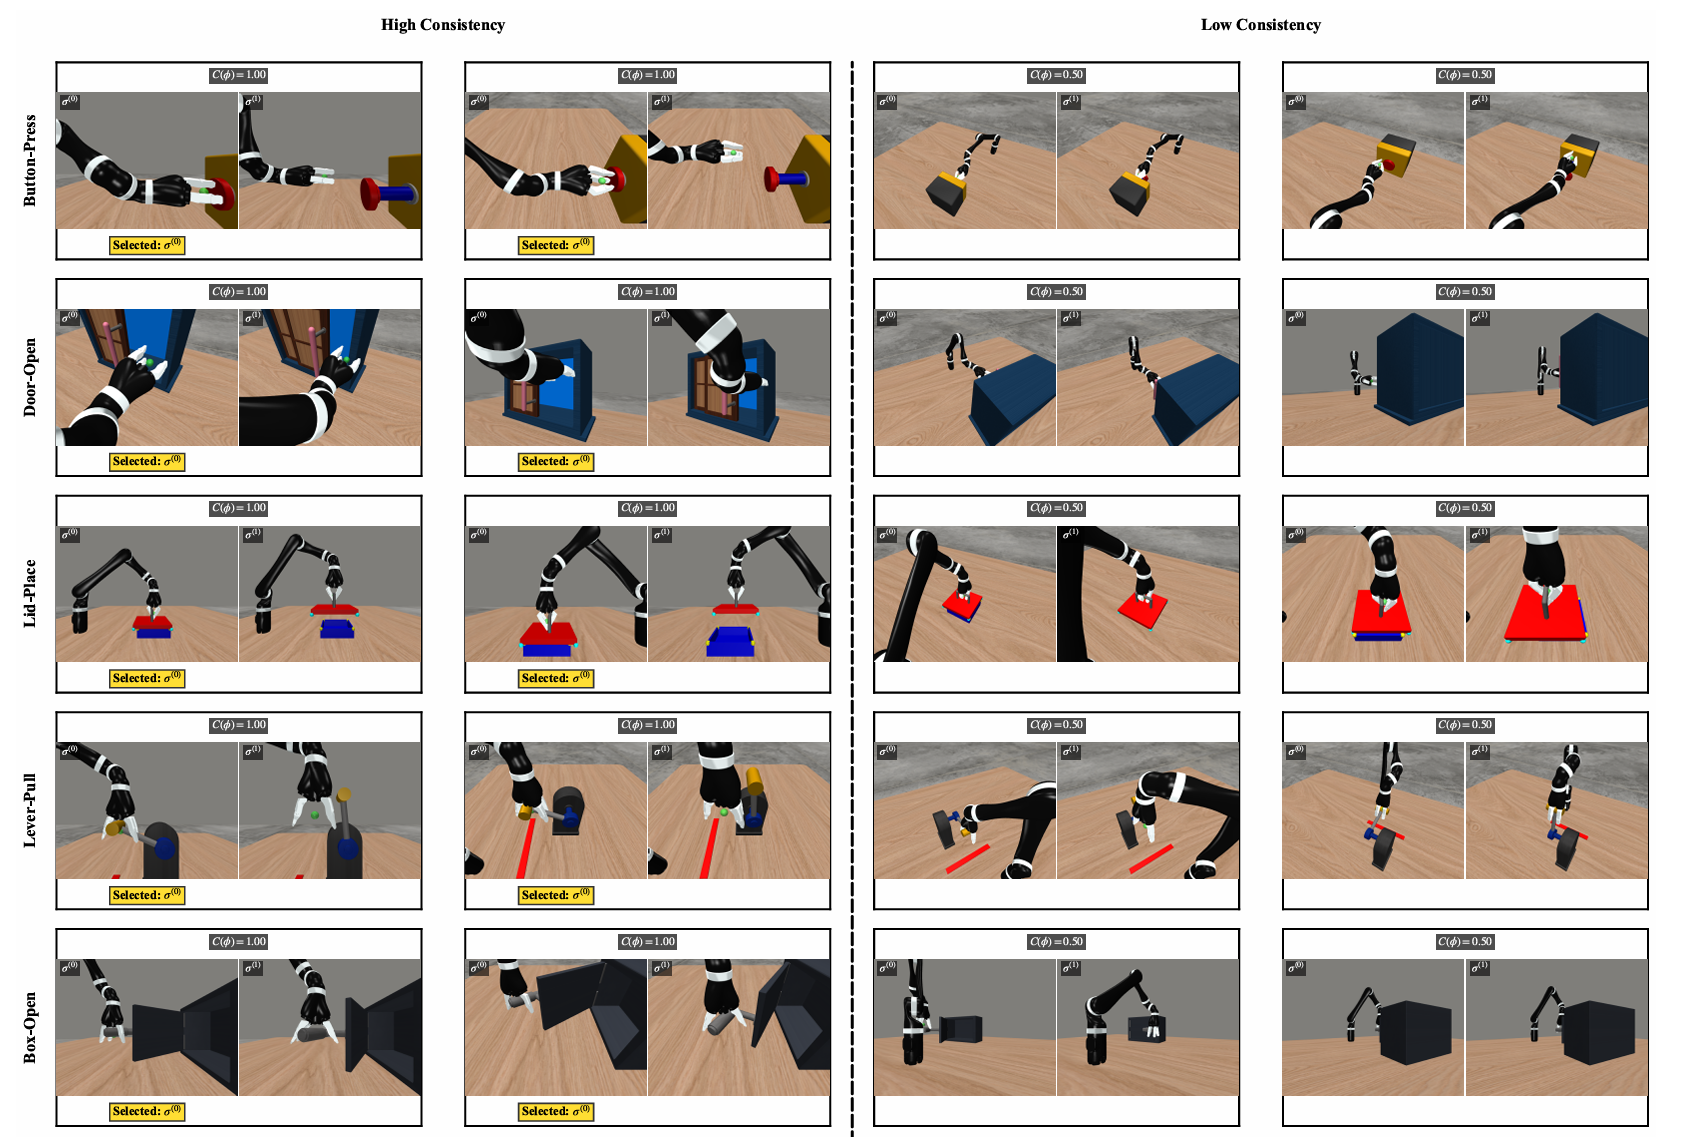
Qualitative examples: optimized viewpoints produce clearer preference comparisons in challenging scenes.
Video
BibTeX
@article{sekiguchi2026pbrlcgvo,
  title={Human-VLM Collaborative Labeling Framework with Consistency-Guided Viewpoint Optimization for Preference-Based Reinforcement Learning},
  author={Sekiguchi, Shunichi and Takahashi, Masaki},
  journal={IEEE Access},
  year={2026},
  doi={10.1109/ACCESS.2026.3721753},
  url={https://doi.org/10.1109/ACCESS.2026.3721753}
}